Alibaba rolls out Wan2.2-S2V, a new speech-to-video AI for lifelike avatars
Alibaba has introduced Wan2.2-S2V, an open-source speech-to-video model designed to generate lifelike animated avatars from portrait photos and audio clips. Positioned as part of the Wan2.2 video generation series, the model enables professional creators to produce film-quality digital humans capable of speaking, singi
Alibaba has introduced Wan2.2-S2V, an open-source speech-to-video model designed to generate lifelike animated avatars from portrait photos and audio clips. Positioned as part of the Wan2.2 video generation series, the model enables professional creators to produce film-quality digital humans capable of speaking, singing, and performing across multiple formats.
Wan2.2-S2V offers flexible framing options, including portrait, bust, and full-body perspectives, while dynamically integrating character actions and environmental elements based on text prompts. By combining text-guided global motion control with audio-driven local movements, the system delivers natural and expressive animations that extend beyond conventional talking-head content.
A key technical advancement lies in its frame processing method, which compresses historical frames into compact latent representations. This approach reduces computational demands and improves stability for long-video generation, a long-standing challenge in animated content production. Output resolutions of 480p and 720p further broaden its applicability across social media and professional use cases.
To support high-quality performance, the research team built a large-scale audio-visual dataset aligned with film and television production needs. Using multi-resolution training, Wan2.2-S2V adapts across vertical short-form content and traditional horizontal formats, making it suitable for diverse creative workflows.
The model is now available on Hugging Face, GitHub, and Alibaba’s ModelScope platform.
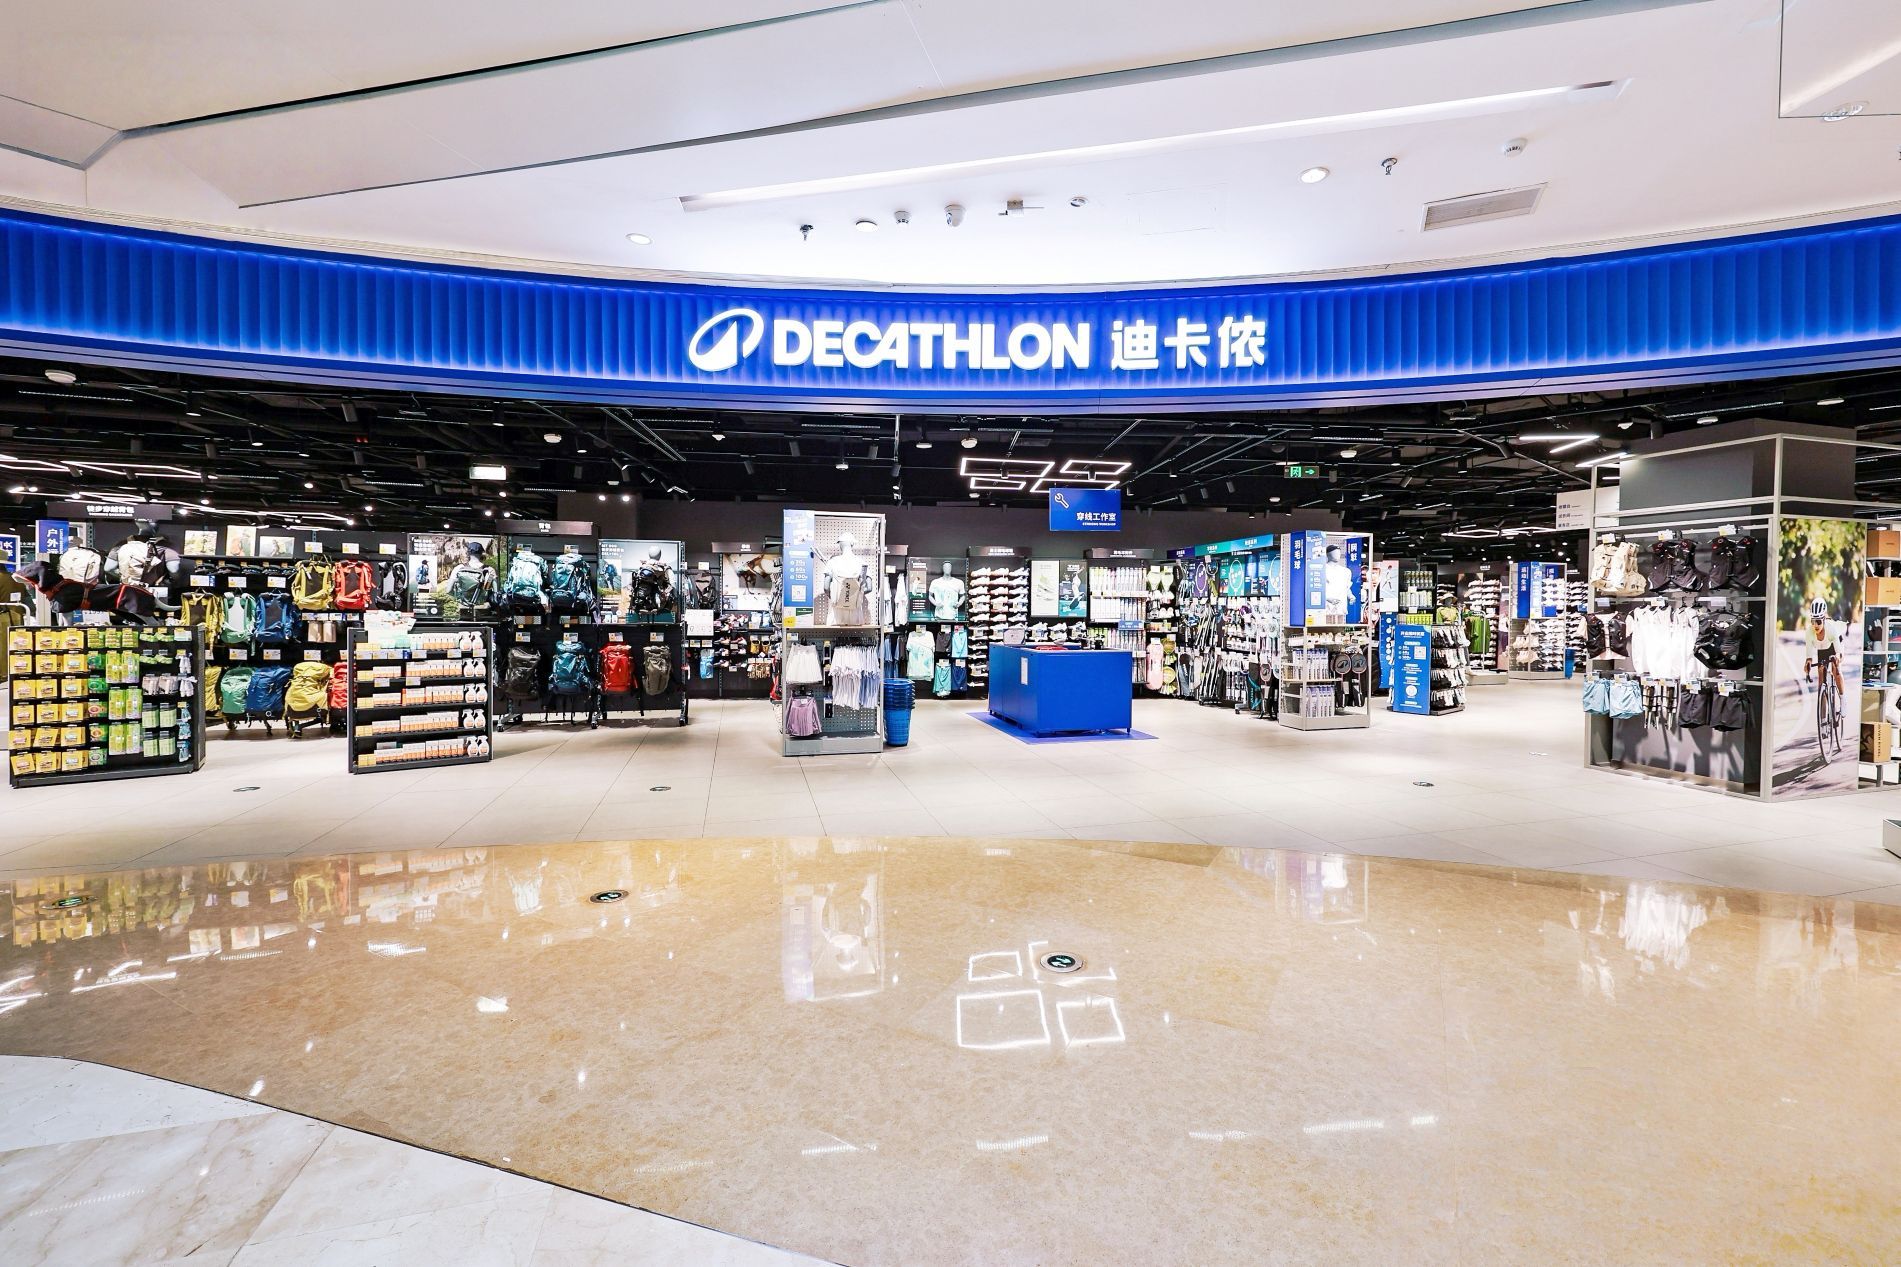
Decathlon China and Tencent Smart Retail are exploring AI applications for customer service, business decisions, employee productivity and store operations.
Google is adding shopping-focused responses to Gemini in Singapore, including product listings, review summaries, comparison tables, pricing and stock checks.
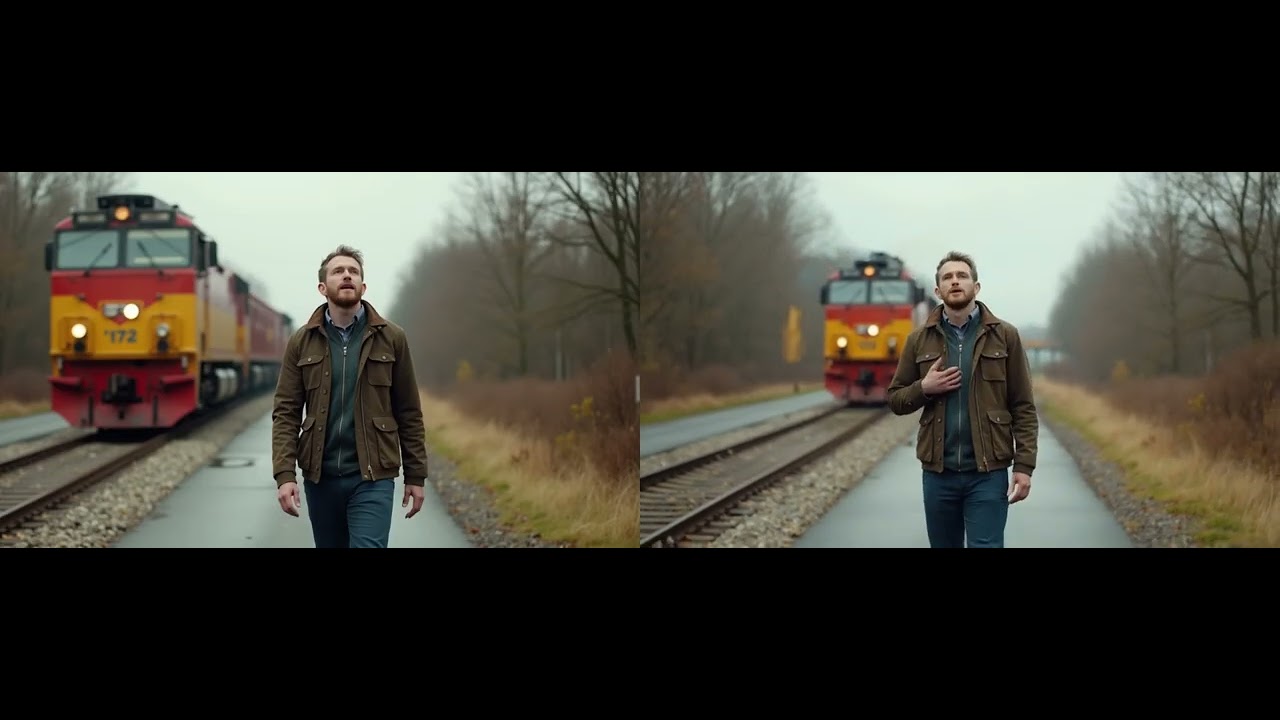
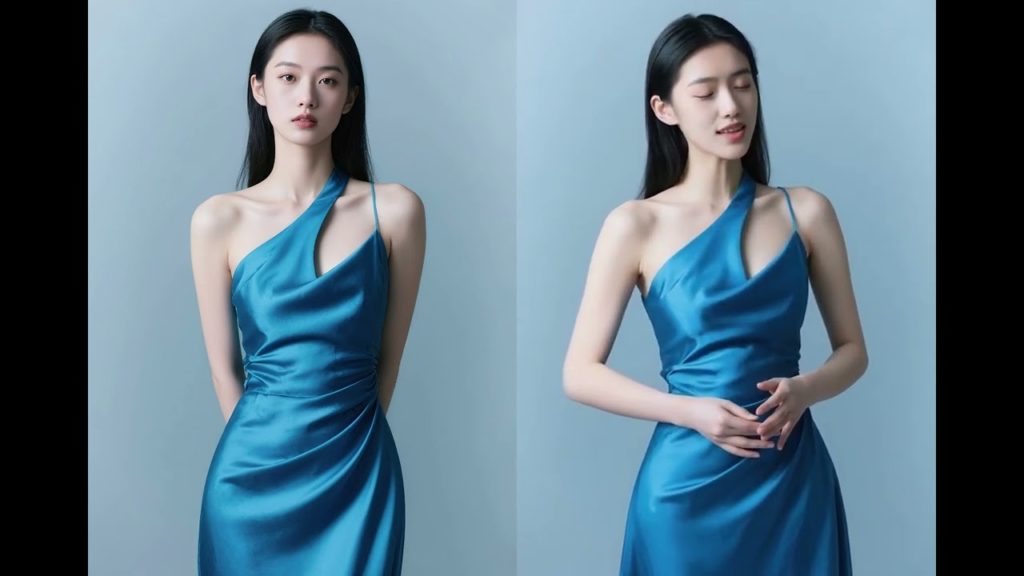 Wan2.2-S2V offers flexible framing options, including portrait, bust, and full-body perspectives, while dynamically integrating character actions and environmental elements based on text prompts. By combining text-guided global motion control with audio-driven local movements, the system delivers natural and expressive animations that extend beyond conventional talking-head content.
 A key technical advancement lies in its frame processing method, which compresses historical frames into compact latent representations. This approach reduces computational demands and improves stability for long-video generation, a long-standing challenge in animated content production. Output resolutions of 480p and 720p further broaden its applicability across social media and professional use cases.
To support high-quality performance, the research team built a large-scale audio-visual dataset aligned with film and television production needs. Using multi-resolution training, Wan2.2-S2V adapts across vertical short-form content and traditional horizontal formats, making it suitable for diverse creative workflows.
The model is now available on Hugging Face, GitHub, and Alibaba’s ModelScope platform.